GenstorAIge [AI90] Training-Inference Solution to Debut at WAIC Future Tech on May 14
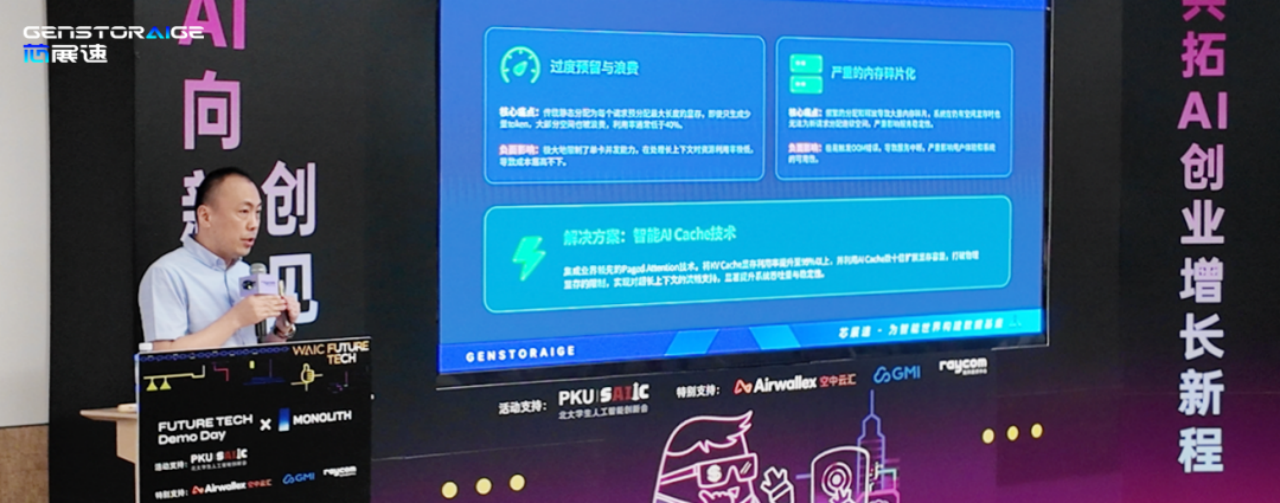
GenstorAIge VP of Products Xu Wei Delivers Keynote at WAIC Future Tech
On May 14, GenstorAIge completed a full technical demonstration of the AI90 training-inference solution and AI90 at the Zhongguancun Financial Technology Information Center in Beijing, becoming one of the companies representing the innovative direction of AI infrastructure.
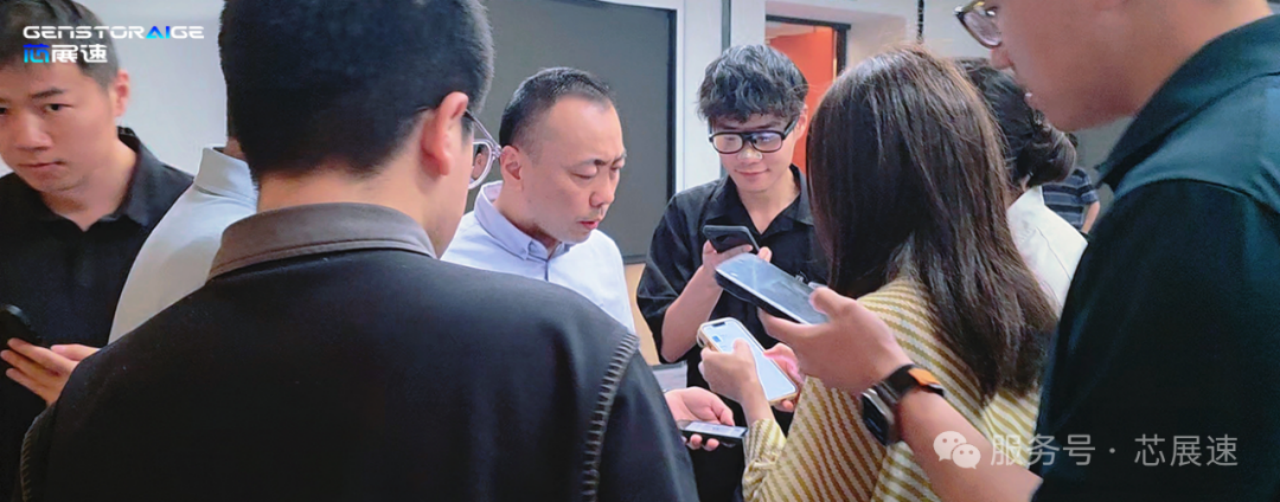
GenstorAIge VP of Products Xu Wei engages in in-depth discussions with peers after the speech
Drawing on 20 years of storage industry experience, GenstorAIge VP of Products Xu Wei presented to judges and on-site industry experts how GenstorAIge breaks through the memory wall bottleneck in large model training, receiving an enthusiastic response.
Industry Pain Points:
How to Break the Memory Wall?
Currently, many developers and enterprises hope to use consumer-grade GPUs for AI inference and fine-tuning, but face two core bottlenecks:
- Limited multi-card parallel efficiency: Default P2P communication on consumer-grade GPUs is restricted, requiring multi-card data to be transferred via the CPU, resulting in high latency and difficulty in linearly scaling cluster performance.
- Difficult long-context processing: Traditional KV Cache memory utilization is typically below 40%, and ultra-long texts (8K+ tokens) easily trigger OOM, making long-document Q&A nearly unusable.
AI90 Solution:
Software-Hardware Synergy Unleashes Consumer-Grade GPU Potential
GenstorAIge's 'AI90 Integrated Software-Hardware AI Inference Acceleration Solution' achieves full-stack optimization from low-level drivers to upper-layer scheduling.
GenstorAIge VP of Products Xu Wei Delivers Keynote at WAIC Future Tech
Intelligent P2P Interconnect
• Through deeply optimized drivers, unlocks the P2P hardware functionality masked in NVIDIA consumer-grade GPUs, enabling direct high-speed point-to-point exchange between multiple cards, bypassing the CPU bottleneck.
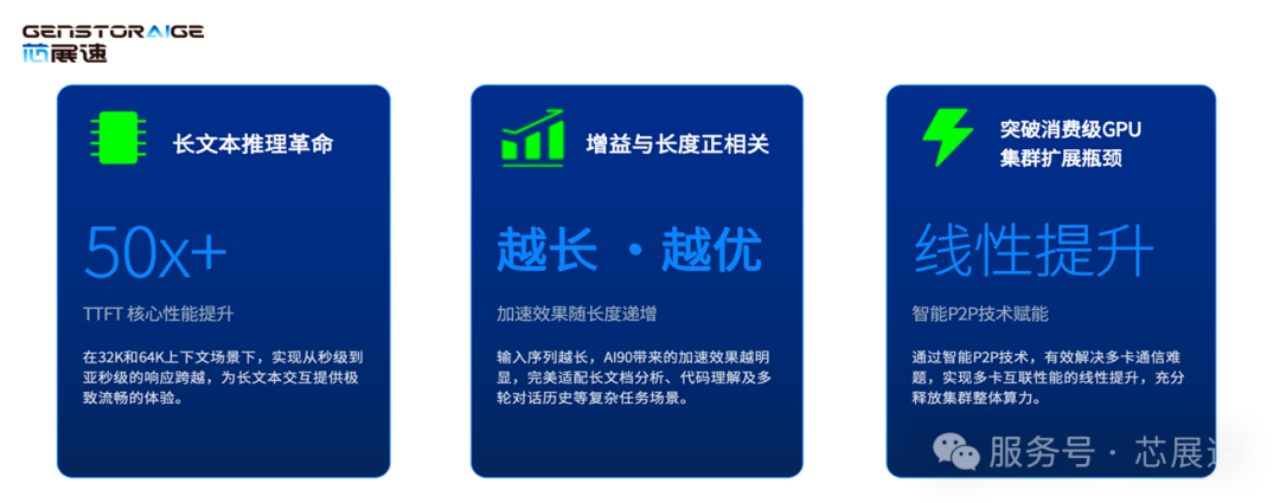
• Multi-card communication latency is reduced to 1/10 of traditional solutions, and multi-card parallel performance is improved by 5.8 times, achieving near-linear scaling.
Intelligent AI Cache
• Integrates Paged Attention technology and utilizes SSDs to expand into TB-level virtual memory, increasing memory utilization from 30%~40% to over 95%. A single card can support 2~3 times the concurrency scale, easily supporting 128K+ ultra-long contexts.
Performance Data (Llama 3 70B Model)
• In 32K and 64K long-context scenarios, TTFT leaps from seconds to sub-seconds, making long document analysis and multi-turn conversational inference smooth and natural.
Core Value: Lowering the AI Computing Power Threshold
The AI90 solution fully taps the potential of consumer-grade GPUs, eliminating the need to purchase expensive HBM or enterprise-grade GPU clusters. Under optimal configurations, it significantly reduces costs, enabling more enterprises to afford the inference and fine-tuning of hundred-billion-parameter models.
Application Scenarios
• AI Model Development and Fine-tuning: Performing LoRA fine-tuning on desktop-grade GPU workstations
• Personal AI Assistant: A local assistant supporting 128K+ ultra-long memory
• Small Team AI Services: Building internal inference APIs at low cost
• AI Research and Education: Utilizing existing x90 series GPU resources for large model teaching and algorithm research
Future Plans
GenstorAIge will continue to iterate the AI90 solution: expanding support for more consumer-grade GPU models, deep model optimization, developing a graphical management interface, and opening standardized APIs to co-build the ecosystem.
Conclusion
GenstorAIge's vision is to build the data foundation for an intelligent world. From enterprise SSDs and Retimer connectivity chips to the AI90 training-inference integrated solution, GenstorAIge leverages full-stack self-developed capabilities to explore a Chinese solution for reducing AI computing costs.
GenstorAIge Building the Data Foundation for an Intelligent World
Official Website:www.gsaitech.com